Automation Exception Handling: Designing Flows That Fail Safely
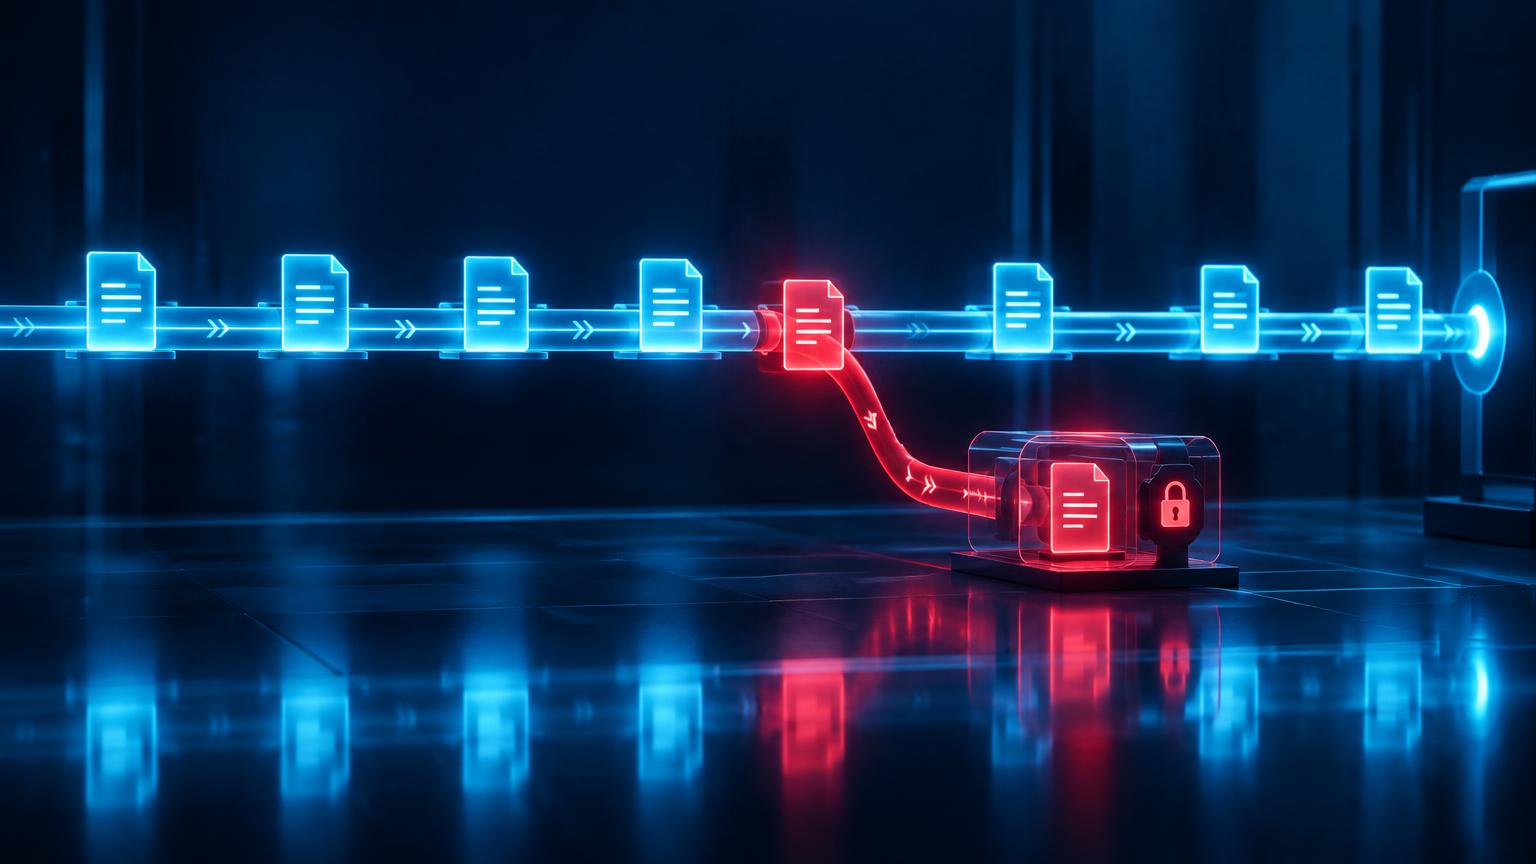
Automation exception handling is how a workflow behaves when something goes wrong: a system is down, a document is missing a field, or a case needs a human decision. It is the difference between an automation that saves time and one that quietly loses invoices, approvals or student records.
Most automation projects spend their time on the "happy path", where every input is clean and every system responds. Real work isn't like that. This guide explains the four kinds of exception, how to handle each one in Power Automate and how to make sure no failed item is ever silently dropped.
Why automations fail quietly
Here is the contrarian part: the automation that worries us most is not the one that fails often. It is the one that hasn't failed in months. Either it is very well built, or its failures aren't being seen.
Power Automate has several behaviours that make quiet failure easy:
- Steps only run after success by default. Each action has "run after" settings for success, failure, skipped and timed out. A new action runs only after the previous one succeeds, so an unhandled failure simply stops the flow (Microsoft Learn training: Implement resilient cloud flows).
- Failing flows switch themselves off. A cloud flow whose trigger or actions fail continuously for 14 days is turned off (Microsoft Learn: Power Automate limits).
- Unanswered approvals expire. A flow run can last up to 30 days, including pending approvals. After that, pending steps time out (Microsoft Learn: Power Automate limits).
- Quiet flows can be suspended. A flow that isn't triggered for 90 days might be turned off, unless its owner has a premium or capacity licence. Owners are told 30 days beforehand (Microsoft Learn).
- Connections and policies change underneath you. Sign-in tokens expire after about 90 days of inactivity, and data loss prevention (DLP) policy changes take effect immediately and can block flows without warning (Microsoft Learn: Fix connection failures).
None of these is a flaw. They are sensible platform rules. But if nobody designed for them, the first sign of trouble is a supplier asking why they haven't been paid.
Four kinds of exception
Not every failure should be handled the same way. Sorting exceptions into four types tells you what the automation should do with each.
| Type | Example | What the automation should do |
|---|---|---|
| Temporary | A system times out or is briefly busy | Retry automatically, with increasing waits |
| Data | An invoice is missing a purchase order number | Stop that item, move it to an exception queue and ask a person to fix it |
| Business rule | A payment is above the approval limit | Route it to a person to decide, by design |
| System | Expired credentials, a DLP block, a changed screen in a desktop app | Stop safely, alert the owner and pause new work until fixed |
The most common mistake is treating everything as temporary and retrying it. Retrying a missing purchase order number a dozen times doesn't fix it. It just delays the moment someone finds out.
Seven principles for automation that fails safely
1. Decide the failure behaviour before you build
For each automation, agree with the process owner what should happen when it can't finish. Should it stop and hold everything, or keep processing other items and set the failed one aside? For payments and student records, stopping safely is usually right. For a daily notification, carrying on is usually fine. Write it down.
2. Retry only what is temporary
Power Automate's default retry policy uses increasing waits. It retries two times on low performance profiles, eight on medium and high profiles without premium connectors, and 12 with premium connectors. You can also set your own fixed or exponential policy, or switch retries off (Microsoft Learn: Cloud flows designer). Increasing waits give a struggling system time to recover rather than hitting it repeatedly. Switch retries off for steps where a repeat could do harm, such as sending a payment.
3. Use try, catch and finally
Microsoft recommends grouping actions into scopes: a "Try" scope for the main work and a "Catch" scope that runs only if "Try" fails (Microsoft Learn: Error handling guidance). Add a "Finally" scope for anything that must always happen, such as logging the outcome. When a scope fails, it reports one failed status, so record which action inside it failed (Microsoft Learn: Scopes).
End the catch path with a Terminate action set to "failed". Otherwise a flow that handled its error can still show as succeeded, and nobody looks at it.
4. Never drop an item: use an exception queue
Every item the automation can't finish should land in one place, such as a SharePoint list or Dataverse table, with the item reference, the reason it failed, the time and who owns the fix. A person works through the queue, fixes the item and sends it back for processing.
The queue is what makes automation trustworthy. Finance and operations teams accept that some items need a person. What they don't accept is items disappearing.
5. Make it safe to run again
When an item is resubmitted, the automation should check what has already happened. Has the invoice already been posted? Has the email already been sent? Without this check, fixing one failure creates a duplicate. Store a unique reference for each item and check it before any step that changes another system.
6. Tell the owner with context, not just "flow failed"
An alert should say which flow, which item, which step and what to do next. Send it to a named owner or a shared team channel, not to the person who happened to build the flow. Where you can, include a link to the run history and to the exception queue.
7. Escalate before things time out
Because pending approvals time out after 30 days, design reminders and escalation well within that. For example, remind the approver after two working days and escalate to their manager after five. For desktop flows, set up "on block error" handling, which can retry with a fixed or exponential policy, then set a variable, run a subflow, continue or stop (Microsoft Learn: Desktop flow control actions).
What about AI agents?
The same principles apply, with one more: decide when the agent should hand over to a person. Where an AI step gives a confidence score, such as reading a document, send low-confidence results to the exception queue rather than acting on them. Where it doesn't, limit what the agent can do without approval, especially anything that changes records or sends money.
Our guide to cloud flows, desktop RPA or AI agents covers which kind of automation suits which task. For running agents as part of the workforce, see non-human resources.
A fail-safe automation checklist
- Name an owner. One person accountable for the automation and its exception queue.
- Classify the exceptions. List the likely temporary, data, business rule and system exceptions, and the response for each.
- Set retries deliberately. Keep them for temporary failures; switch them off for steps that must not repeat.
- Wrap the work in try, catch and finally scopes. Terminate as failed on the catch path.
- Build the exception queue. Every unfinished item goes there with a reason and an owner.
- Make resubmission safe. Check for a unique reference before changing anything.
- Run flows under service accounts. Avoid personal connections that break when someone leaves or a token expires.
- Agree DLP changes in advance. Ask your Power Platform admin to tell automation owners before connector policies change.
- Test the failures, not just the happy path. Before go-live, deliberately send a bad input, switch off a connection and leave an approval unanswered.
- Measure and review. Track exceptions monthly and fix the causes of the most common ones.
What to measure
- Straight-through rate: the share of items completed with no human touch.
- Exception rate by type: temporary, data, business rule and system.
- Time to clear an exception: from landing in the queue to being resolved.
- Silent failures: items found missing that never reached the queue. The target is zero.
Put the headline measures on your operational KPI scorecard. If the same data exception keeps appearing, it is a process problem upstream, and it belongs on your continual improvement register. That is often where the biggest gain is: fix the form or the supplier instruction, and the exception disappears.
An illustrative example
The details below are illustrative, not from a client.
A logistics company automates supplier invoice processing. Invoices arrive by email, are read and matched to purchase orders, and are posted to the finance system. In the first version, a missing purchase order number causes the flow to fail, and after a fortnight of failures the flow is switched off. Nobody notices until suppliers start chasing payments.
The rebuilt version sorts exceptions into the four types. Finance system timeouts are retried. Invoices without a purchase order go to an exception queue in SharePoint with the reason, and the accounts payable team clears them daily. Invoices over the approval limit go to a manager, with reminders after two days. Expired credentials stop the flow and alert the owner. Each invoice carries a unique reference, so resubmitted items are never posted twice.
After a month, the queue shows that most exceptions come from three suppliers who leave off purchase order numbers. The finance team contacts them, and the exception rate falls.
How Cyber Samurai helps
Our automation team designs and builds Power Automate cloud flows, desktop flows and AI-assisted automation, with exception handling, queues, alerting and service accounts built in from the start. For automations already in place, we review how they fail, fix the gaps and set up monitoring.
Our Automation Opportunity Assessment finds the processes worth automating and the existing automations most at risk of silent failure. Book a consultation to talk it through, or browse 20 Power Automate workflow examples for ideas. Where agents are involved, our AI Management as a Service covers oversight and control.
This article is part of our operational excellence series. Automation works best on a process that has already been simplified, which is the focus of our process improvement page. For moving from firefighting to early warning more generally, see our guide to reactive and proactive monitoring.
Book a consultation · Explore automation
Questions
Frequently asked
- Automation exception handling is the design of what a workflow does when it can't complete normally. Good exception handling retries temporary problems, sends data and business-rule exceptions to a person, stops safely on system errors and makes sure no item is lost.
Keep reading